Which parts of a camera image do you need to see clearly to answer a specific question? Seeing More with Less: Human-like Representations in Vision Models, by Andrey Gizdov, Shimon Ullman, and Daniel Harari, studies how vision models can work with detail concentrated around points of focus.
For a business using cameras, that suggests a useful starting point: define the task before choosing what to look at. The examples below explain that setup decision, not additional benchmark results. The research overview explains the paper’s method with an interactive comparison.
Let the task define the region
A checkout exception depends on the scanner and bagging area. A line-side inventory check depends on the configured part and its staging position. The most visually striking part of a frame may have little to do with either decision.
Start with a question such as “Was this item scanned before it entered the bag?” Then choose a view that shows both actions. A close-up of the bag alone cannot answer it.
Test the cases that look similar
An empty staging position and one hidden briefly by a passing worker require different conclusions. A pallet in a storage area is different from one left inside a pedestrian route.
Test both cases before running the workflow. Also check changes in lighting, camera angle, and obstructions. More detail will not reveal a part hidden behind a worker.
Explore the comparison
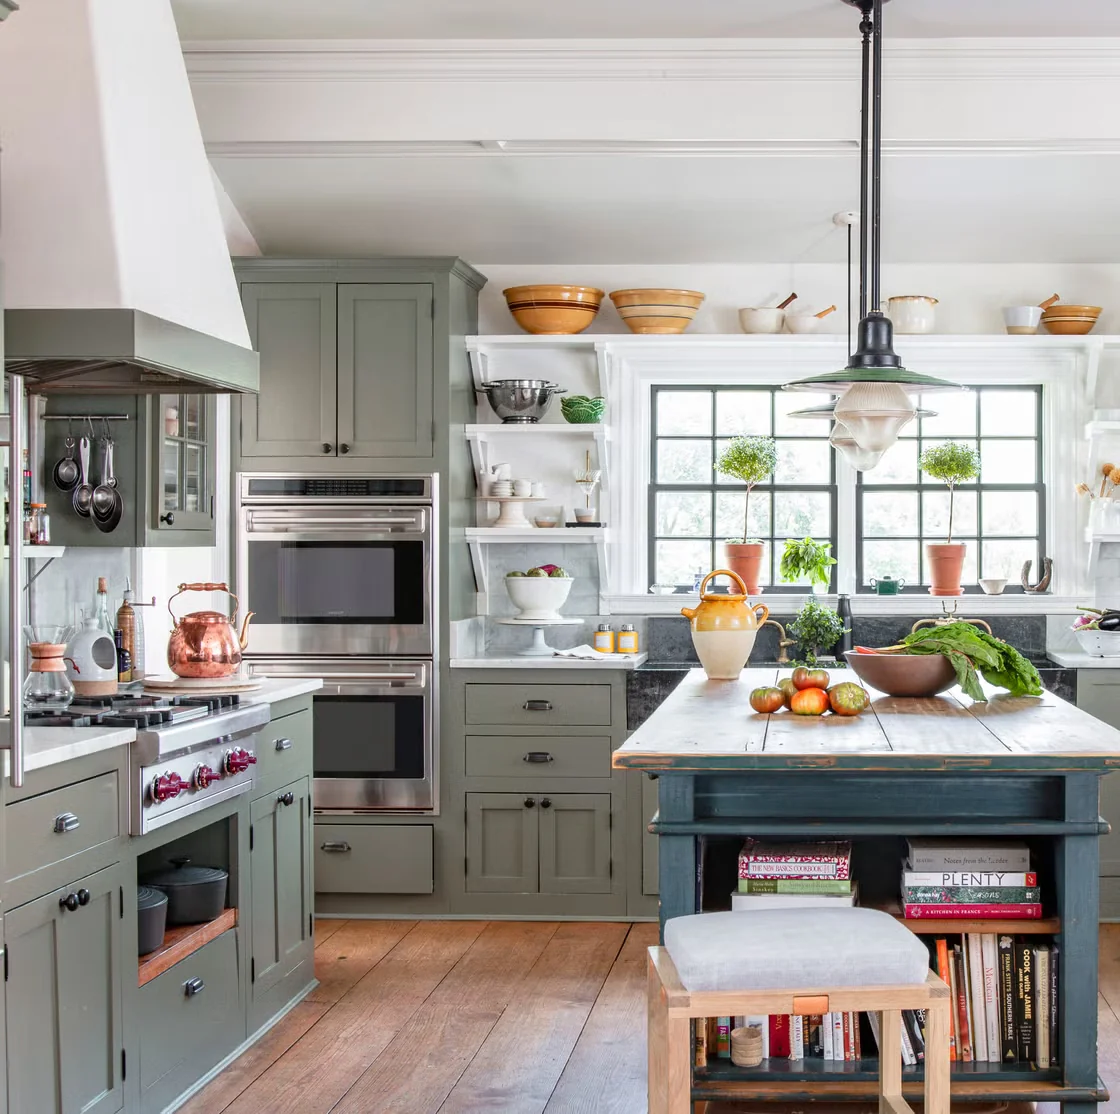
The interactive comparison uses a kitchen image and the preset “Find me the food.”
The comparison follows a preset path to show how sampling works. For the evaluation setup and measured results, read the linked paper.
Connect the observation to a decision
Decide what happens in three cases: the condition is met, it is not met, or the camera cannot tell. For an inventory check, that might mean requesting a restock, making no change, or asking someone to review the clip.
Keep the item reference, location, time, and clip with the result. The person receiving the task should be able to see why it was created.
Sources
Seeing More with Less: Human-like Representations in Vision Models
Andrey Gizdov, Shimon Ullman, Daniel Harari