Research / Visual attention

Seeing more
with less.

We’ve developed the most bandwidth efficient & lowest latency vision model inference engine.

See the difference

One scene. Two ways to look.

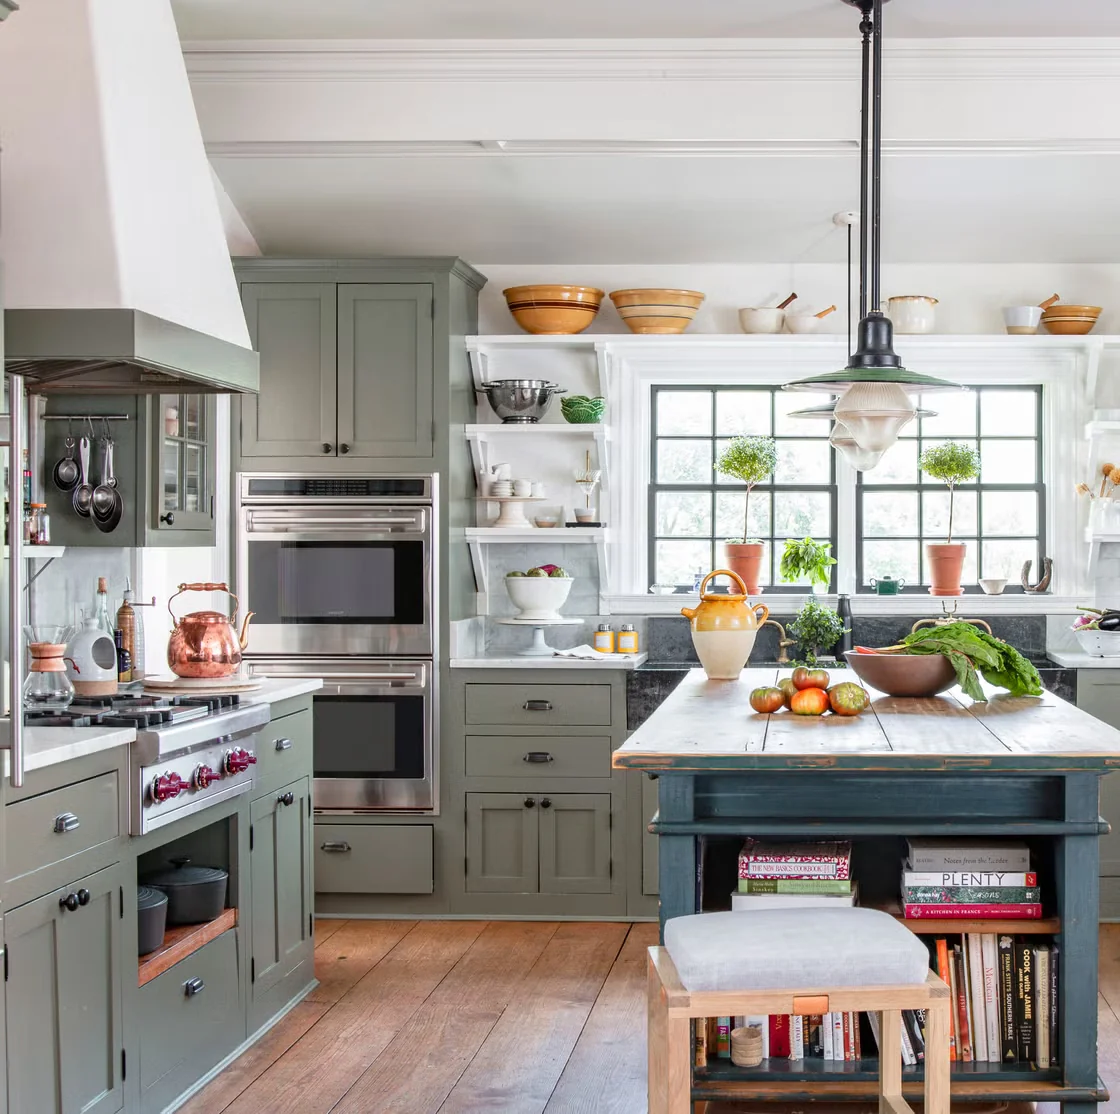
Click Search to watch both models find the food in the same scene.

Kitchen frame ready for visual search
Kitchen-Frame.jpeg Loading demonstration
Loading
16 / 2,000
The bottleneck

More pixels.
More to process.

We’ve built a vision language model inference engine that can work on live video, in real time, using 33x less bandwidth and up to 990x less compute.

From observation to action

Explore how this works
in OpenVector.

Choose what to watch for and what should happen when the camera sees it. Review the steps in the platform demo.